

November 23, 2023 · 2 min read
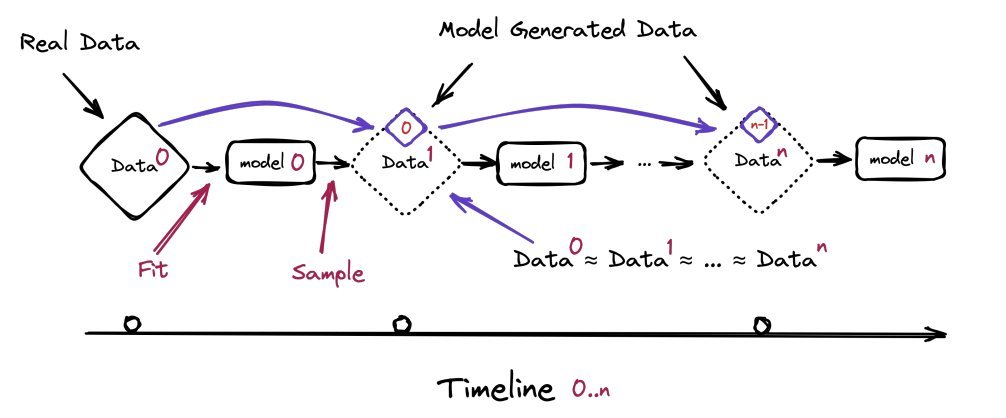
The Curse of Recursion: Training on Generated Data Makes Models Forget
Can we use synthetic data to train future generations of LLM's?
Keep up-to-date on the latest product updates, how-tos, industry insights, and community spotlights.
Can we use synthetic data to train future generations of LLM's?
Identify a key shortcoming of LLMs in terms of their causal inference skills.
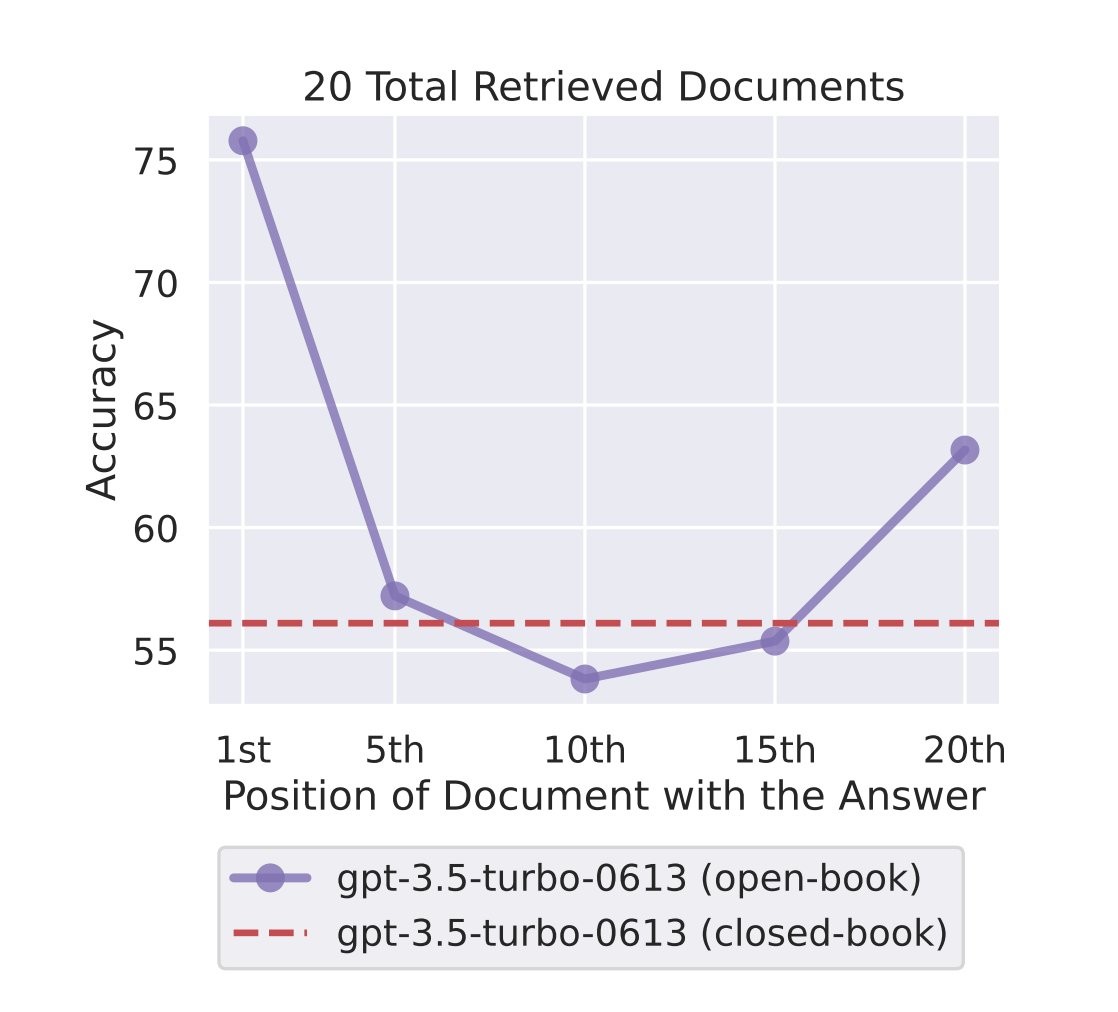
Why do large language models attend better over the beginning and end of thier context?
Comparing LLM performance using retreival vs longer context lengths.