September 22, 2026 · 17 min read
Agent Memory with Engram: A Practical Guide
Learn how to use Engram effectively, from writing topic descriptions that control extraction to choosing bounded topics and scopes, selecting a retrieval mode, and placing memories in your prompt without hurting prompt-cache efficiency.
September 9, 2026 · 14 min read
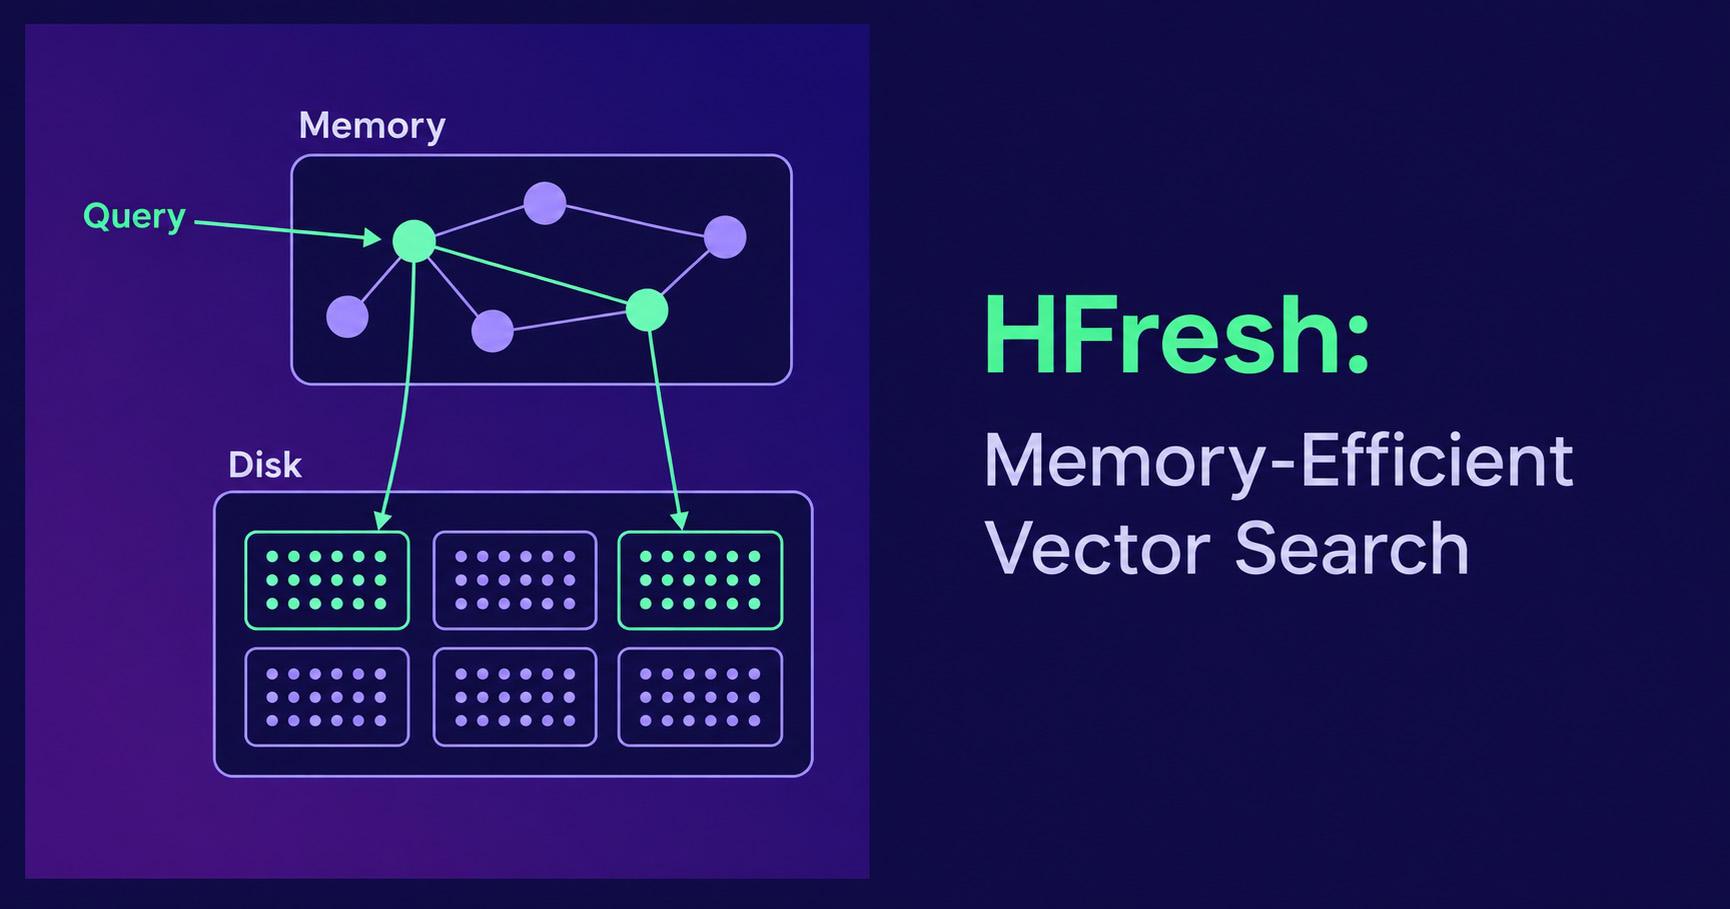
HFresh: Memory-Efficient Vector Search
HFresh is Weaviate's disk-based vector index for memory-efficient vector search, combining low heap usage with incremental background maintenance.
July 21, 2026 · 9 min read
Query Profiling: See Where a Slow Query Spends Its Time
When a Weaviate query is slow, the first question is where the time went. Query profiling returns a per-stage, per-shard timing breakdown, making query performance issues visible.
June 18, 2026 · 11 min read
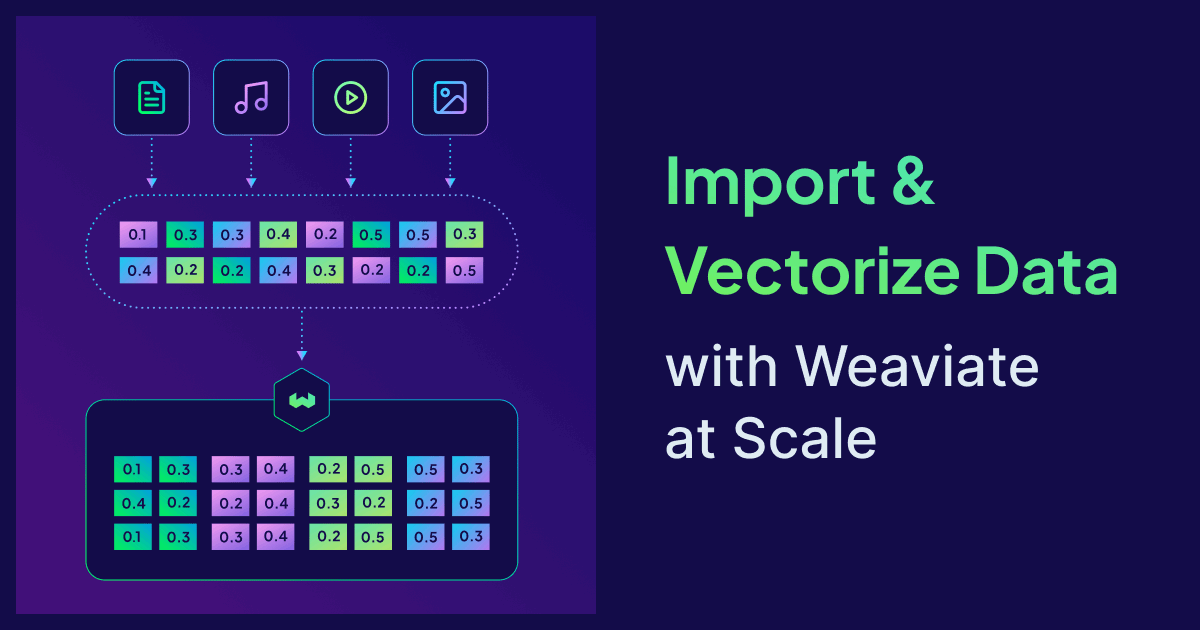
Import & Vectorize Data with Weaviate at Scale
Server-side batching, retries, the blobHash data type, and multimodal ingestion — what to use when, with code.
May 14, 2026 · 12 min read
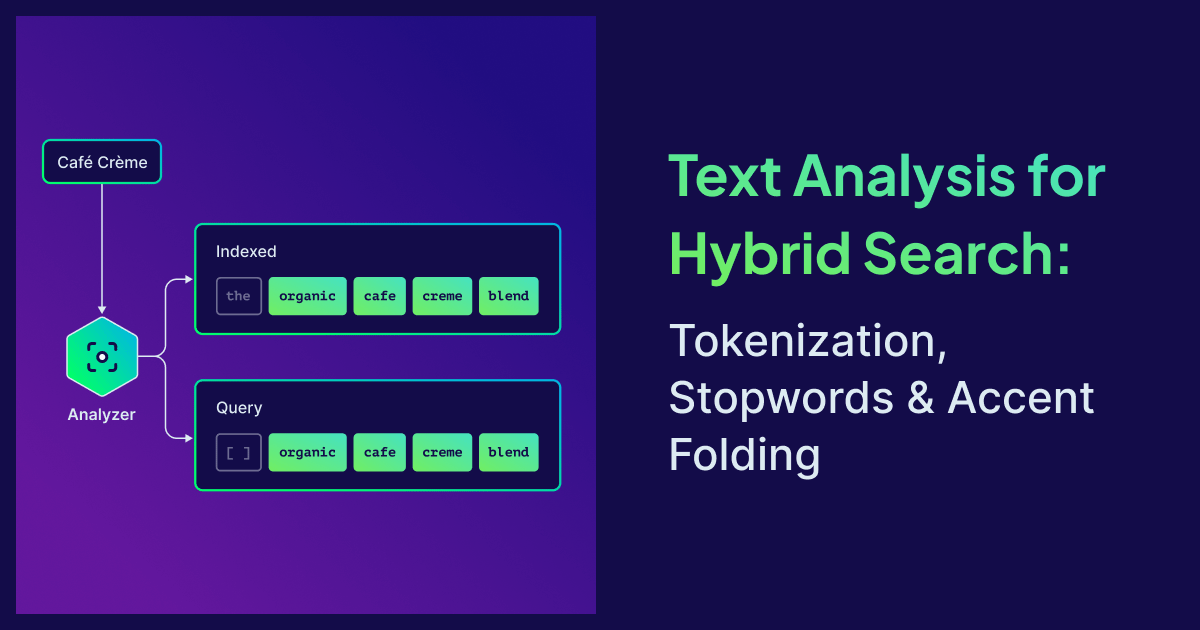
Text Analysis for Hybrid Search: Tokenization, Stopwords & Accent Folding
Tokenization makes or breaks hybrid search. See how Weaviate's accent folding, custom stopwords, and /v1/tokenize endpoint power multilingual BM25.
May 6, 2026 · 11 min read
Your LLM Is Only as Good as What It Retrieves
A Researcher's Perspective on Retrieval Quality in RAG Systems
April 21, 2026 · 18 min read
Engram: Memory by Weaviate
A deep dive into Engram, our managed memory service for agents which is simple to get started but adaptable to any use case.
April 2, 2026 · 10 min read
Oh Memories, Where'd You Go
Two weeks of dogfooding Engram, Weaviate's memory product, in daily Claude Code sessions. This surfaced where a dedicated memory product adds value, and the specific mechanics that prevent integration with coding assistants from working well.
February 4, 2026 · 9 min read
The Limit in the Loop
Memory isn't just a feature for AI applications—it's infrastructure. As agents scale, the limited loop of stateless interactions breaks down, and continuity becomes a systems problem that requires active maintenance.
December 9, 2025 · 21 min read
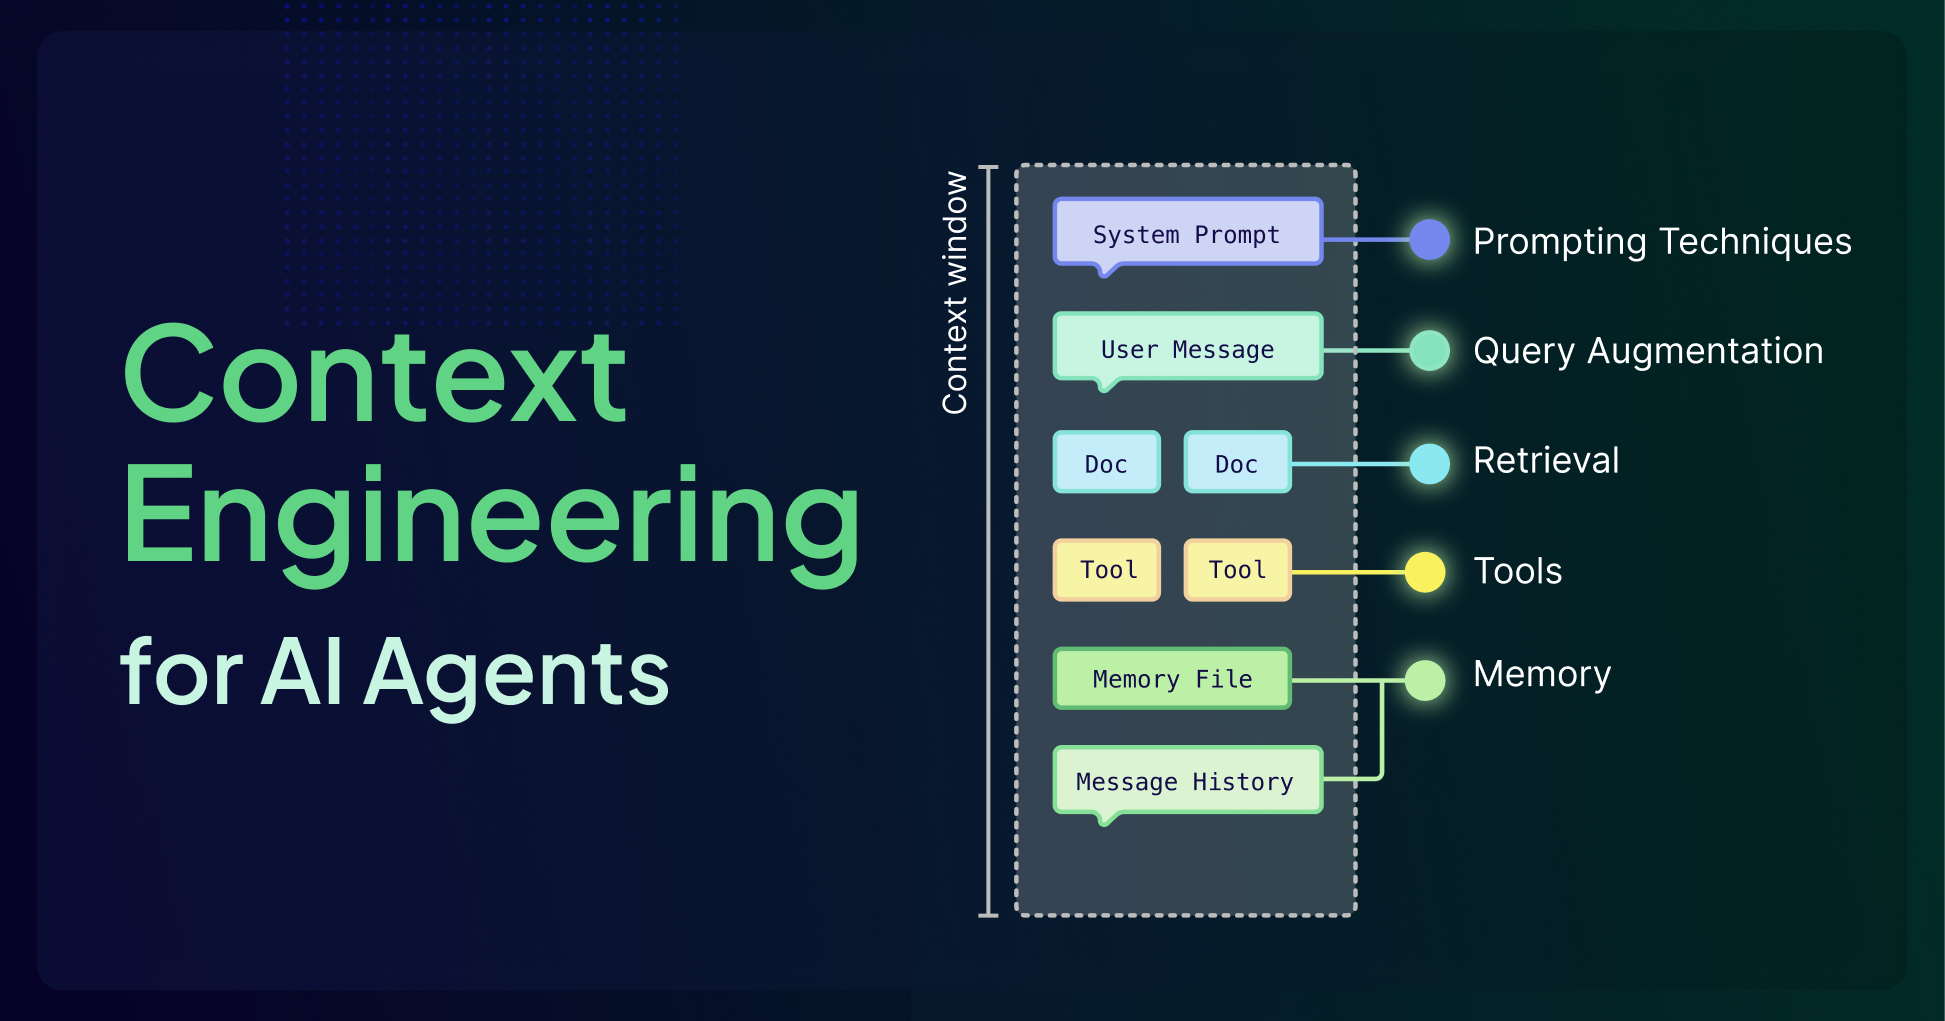
Context Engineering - LLM Memory and Retrieval for AI Agents
Context engineering is how AI agents manage LLM memory—selecting, retrieving, and organizing context from short-term and long-term memory to improve reliability in production.
November 4, 2025 · 21 min read
Evals and Guardrails in Enterprise workflows (Part 3)
Hands-on patterns: Design pattern for gen-AI enterprise applications, with Arize AI.
October 9, 2025 · 13 min read
When Good Models Go Bad
A strategic guide to the costs, risks and rewards of upgrading embedding models in production AI